Agents that act in your systems,
only after they pass your tests.

Bounded agents that act inside your systems, released only after they pass the tests your team agrees.

  • Tested before release

    Each version passes its evaluation suite before users meet it.

  • Scoped to the task

    A known identity and only the tools the task needs.

  • Watched in production

    Quality, latency and cost tracked after launch.

Pilot in four to six weeks, typically · Fixed price · The evaluation design is yours

Your casesGateYour systems

A useful agent ships
against a release standard.

ToolsDemoNo evidenceRelease standardPermissionsCases passedAction

Once an agent can call a business tool, it has moved from answering to acting. A demo cannot tell you what it may do, or whether the next version is safe to release.

  • Bound the action

    Identity and tool scopes define what the agent may do.

  • Ground it in your data

    Governed business context, with answers that carry their sources.

  • Let tests pick the model

    Your test cases compare quality, cost and latency, not benchmark reputation.

This is the right engagement when

  • A bounded task needs an agent that uses business tools or takes actions.
  • An agent demo worked, and now it has to act inside real systems.
  • The data, controls and success baseline are ready for a Pilot.
  • A live agent needs repeatable evaluation and release discipline.

Bound the action.
Evaluate the release.

Four stages take one bounded task from an agreed action boundary to a released agent under watch.

Agent boundaryAgent designGround and connectGrounded tool pathModel choiceEvaluation suiteRelease and watchRelease evidenceTaskIdentityApprovalAgentGoverned dataContextTool registryQualityCostLatencyRegressionReleaseWatchNext version
  1. Define the task, its identity, the allowed tools and where a person decides.

    You receive

    Agent design

    The task, identity, tool scopes and guardrails, written down before the build.

The Mandelbulb Kit Agentic AI edition

Engineered in-house.
The Mandelbulb Kit.

Accelerators, agents and products we build and maintain ourselves, brought into an engagement wherever they fit.

Systems of recordRuntimeAudit trailTool call

Agent runtime · Runs the agents

Blumcore

The runtime every Kit agent runs on, built to act inside the systems you already run.

  • Reads enterprise data through MCP-native connectors
  • Acts inside systems of record through tool calls, not screen scraping
  • Runs in the cloud, on-premise or air-gapped, every action audited

Plugs into Ground and connect

Explore more about Blumcore
What this is not.

This service starts with a funded, bounded task and ends with an agent released and watched in production.

The story this service stands on.

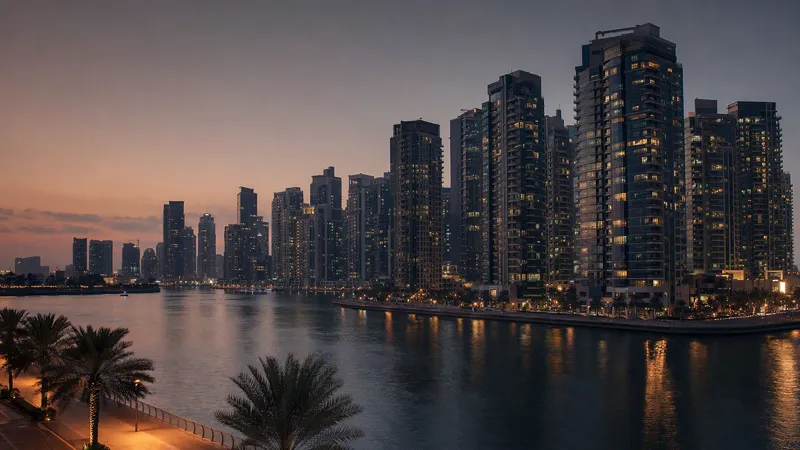
Residential towers with lit balconies across a calm water channel at dusk, a palm-lined promenade in front

Danube Group

Real estate · Building materials

Faster customer response
70%
Less manual customer-service intervention
60%
Lower error rate in interactions
75%

How Danube Group Cut Response Time 70% With a Bilingual AI Assistant

Reaching a Danube Group salesperson meant a slow path that left prospects waiting. We built Aisha, an English and Arabic assistant on Azure OpenAI that captures contact details and project interest, offers an IVRS call-back and books site visits directly in chat, with a responsible-AI guardrail keeping its answers to the group’s own content and every conversation captured in Fabric KQL. Response time fell 70%, errors in interactions fell 75% and manual intervention fell 60%.

The assistant runs on Azure OpenAI and the Microsoft Bot Framework.

Explore Real Estate

Questions buyers ask.

What is agentic AI in an enterprise?

Agentic AI is software that can plan a response and call business tools, so it acts in your systems instead of only answering questions. That makes the engineering question what it may do, which evidence it needs and how the team knows a new version is safe to release. We build bounded agents with a known identity, scoped tools, grounding in your data and an evaluation gate before release.

How do you test an AI agent before it goes live?

Every version passes an evaluation suite your team agrees before users meet it. The suite holds the test cases and pass criteria the agent must clear, including the difficult cases a demonstration can miss. Regression tests run before every release, and after launch quality, latency and cost are watched in production, so each new version has a controlled path into use.

How do you choose the LLM for an AI agent?

Your test cases choose it, not benchmark reputation. Each candidate model route is compared on quality, cost and latency against the evaluation suite for your task, and the evidence picks the model. Because the decision rests on tests, the chosen route can change as the evidence changes, and the release gate gives that change a controlled path into production.

How long does it take to build a production AI agent?

The Blueprint phase typically takes two to three weeks, and the Pilot that follows typically takes four to six weeks, each at a fixed price. The Blueprint designs the agent boundary, identity, guardrails and evaluation suite. The Pilot takes one bounded agent to an evaluated production slice, and expansion then runs on a quarterly rhythm. You keep the evaluation design even if you stop after the Pilot.

What has to be ready before an AI agent Pilot starts?

A funded, bounded task, with its data, controls and success baseline ready. If the use case has not been tested for that, AI Readiness is the step before this one. The task should name the tools the agent needs, the identity it acts under and where a person still decides, because those become the agent design written down before the build.

More in Data & AI.

All of Data & AI

Natural next step

Natural next step: Trust Layer, Data & AI

Carry the agent’s control design into the request path and production watch.

  • StreamRuleAction

    Real-Time Intelligence

    Operational events become live KPIs and alerts, with a path from each event to an action.

  • SourcesCheckedConformed

    Data Integration

    Incoming data is checked at the boundary and lands as reusable feeds in a governed lakehouse.

  • QuestionSemantic modelGold layer

    Analytics & BI

    Governed semantic models on Power BI or Looker, with metric definitions your team can inspect.

  • IdentitySafetySource

    Trust Layer

    Identity, policy, safety and traceability sit in the request path, so every action leaves an auditable trail.

Bring one bounded task.
Set the standard to ship.

Book a 30-minute working session on one bounded task, its tools and the tests it must pass.