Fund the right bets.
Kill the rest in writing.

Turn a long list of data and AI ideas into a costed, ordered roadmap, with a written verdict on every idea.

  • A verdict on every idea

    Build, Buy, Pilot, Delay or Don’t build, in writing.

  • Every survivor costed

    A build cost, a run cost and a time to value.

  • Ordered and owned

    A stated sequence and a named owner for every funded bet.

Scoped in the first working session · Fixed price · The roadmap is yours

Fund in orderDelayDon't build

A strategy that decides
is one the board can fund.

Funds everythingDecidesBuildBuyPilotDelayDon't build

Most use-case lists reach the board ranked by enthusiasm, none costed, none owned. The board applauds and funds nothing, while pilots keep running on separate stacks with no before-number.

  • No is a verdict

    Don’t-build verdicts are written down beside the builds, so the budget goes to the bets that survive.

  • Ordered by dependency

    Early bets leave behind the data and platform that later bets reuse.

  • Measured from the start

    Every benefit gets a baseline before work starts, so its value can be audited.

This is the right engagement when

  • There are more data and AI ideas than budget to fund them.
  • Pilots run on separate stacks, each with its own measure of success.
  • The board asks what the AI budget buys, and the answer is a list.
  • The estate is measured, and the open question is which bets, in what order.

A long list in.
A costed sequence out.

Seven steps take a long list to a costed, owned sequence and a backlog ready to build.

CollectScreenNeedsCostBaselineSequenceBacklog
  1. Every candidate goes on one list: streams, reports, models and agents side by side, with the Assess shortlist where one exists.

    You receive

    Candidate list

    Every idea in one place, competing for one budget.

The Mandelbulb Kit Data & AI Strategy edition

Engineered in-house.
The Mandelbulb Kit.

Accelerators, agents and products we build and maintain ourselves, brought into an engagement wherever they fit.

Use caseFour scoresVerdictSuitabilityReadinessValueRiskBuildBuyPilotDelayDon’t build

Use-case screen · Screens every bet

Butter

A free first verdict on one AI use case, in about two minutes, with no call.

  • Asks eleven short questions about one use case
  • Scores suitability, readiness, value and risk
  • Returns one of five verdicts: Build, Buy, Pilot, Delay or Don't build

Plugs into Screen the list

Explore more about Butter
What this is not.

This work ends in a funded, ordered roadmap. Nothing is built inside it.

The story this service stands on.

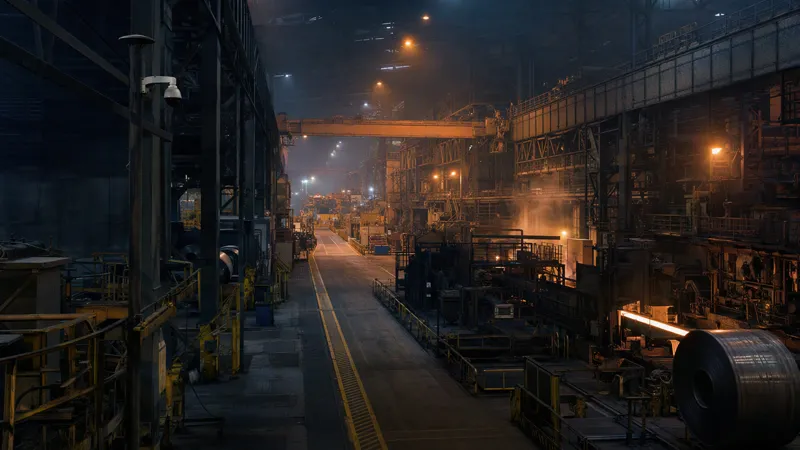
An empty plant floor on the night shift, yellow safety walkways, large machines and cameras mounted on steel columns

An industrial materials manufacturer

Manufacturing · Workplace safety

Less time spent on manual checks
60%
Lower safety-monitoring cost
30%

Computer Vision for PPE Compliance: 100K+ Safety Issues Detected

Manual PPE checks at an industrial materials manufacturer were inconsistent and could not scale to round-the-clock operations. Once manual inspection was confirmed as not accurate enough, we built one bounded bet: computer vision that detects masks, gloves, helmets and jackets and records violations 24/7. Time spent on manual checks fell 60% and safety-monitoring cost fell 30%, each against the manual process it replaced.

The platform was designed to deploy from one site to many, so the first deployment leaves a pattern the next site can reuse: the kind of early bet a roadmap orders first for what it leaves behind.

Explore Manufacturing

Questions buyers ask.

Will you only recommend work you can build for us?

No. Don’t build is one of the five verdicts, and here a don’t-build verdict is a deliverable: it is written down beside the builds, with its reason. The price is fixed up front, so it does not move with what the roadmap recommends. The backlog is written for any capable team to start from, and you keep the roadmap, the backlog, the operating model and the benefit baselines whoever builds from them.

We have not measured our estate yet. Do we start here?

Not if the estate has never been measured. Start with the Data Strategy Assessment: typically two weeks, and you keep the findings either way. Its use-case shortlist comes into this engagement with the rest of your list, and each case gets its verdict here. If the estate is already known and the open question is which bets to fund, and in what order, start here.

What happens once the roadmap is funded?

Each bet leaves by its own route, in sequence order. An agent bet that has not had its readiness pass takes it before anyone builds it, a bet that needs the estate moved goes to Modernization, and the rest go to Data & AI for a Pilot of typically four to six weeks: one fixed-scope production slice on your own data, at a fixed price, judged against an agreed success metric. The backlog is then worked on a quarterly rhythm, with a written recap every week.

More in Strategy & Advisory.

All of Strategy & Advisory

Natural next step

Natural next step: AI Readiness, Strategy & Advisory

When the first funded bet is an agent that has not had its readiness pass, the roadmap and that bet's backlog entry cross to AI Readiness, and the question changes from which bets to fund to whether your estate can carry this one.

  • AssumedMeasuredCosted map

    Data Strategy Assessment

    We read your estate as it runs, typically in two weeks. You keep a costed modernization map with its TCO delta.

  • OwnerAccessDataset

    Data Governance

    Owners, access tiers and lineage are decided before the next workload lands, in a governance model the platform enforces.

  • TodayAt scaleVerdict

    Technology Selection

    Fabric, Databricks or the platform you run today, settled on the few workloads that carry the decision, before any migration is funded.

  • ControlsDataBaseline

    AI Readiness

    One agent is measured before it is built: Butter's free verdict, then typically two weeks on its data, controls and evaluation baseline.

Bring the list
you cannot fund in full.

Bring your use-case list, ranked or not, and the pilots already running to a 30-minute working session.